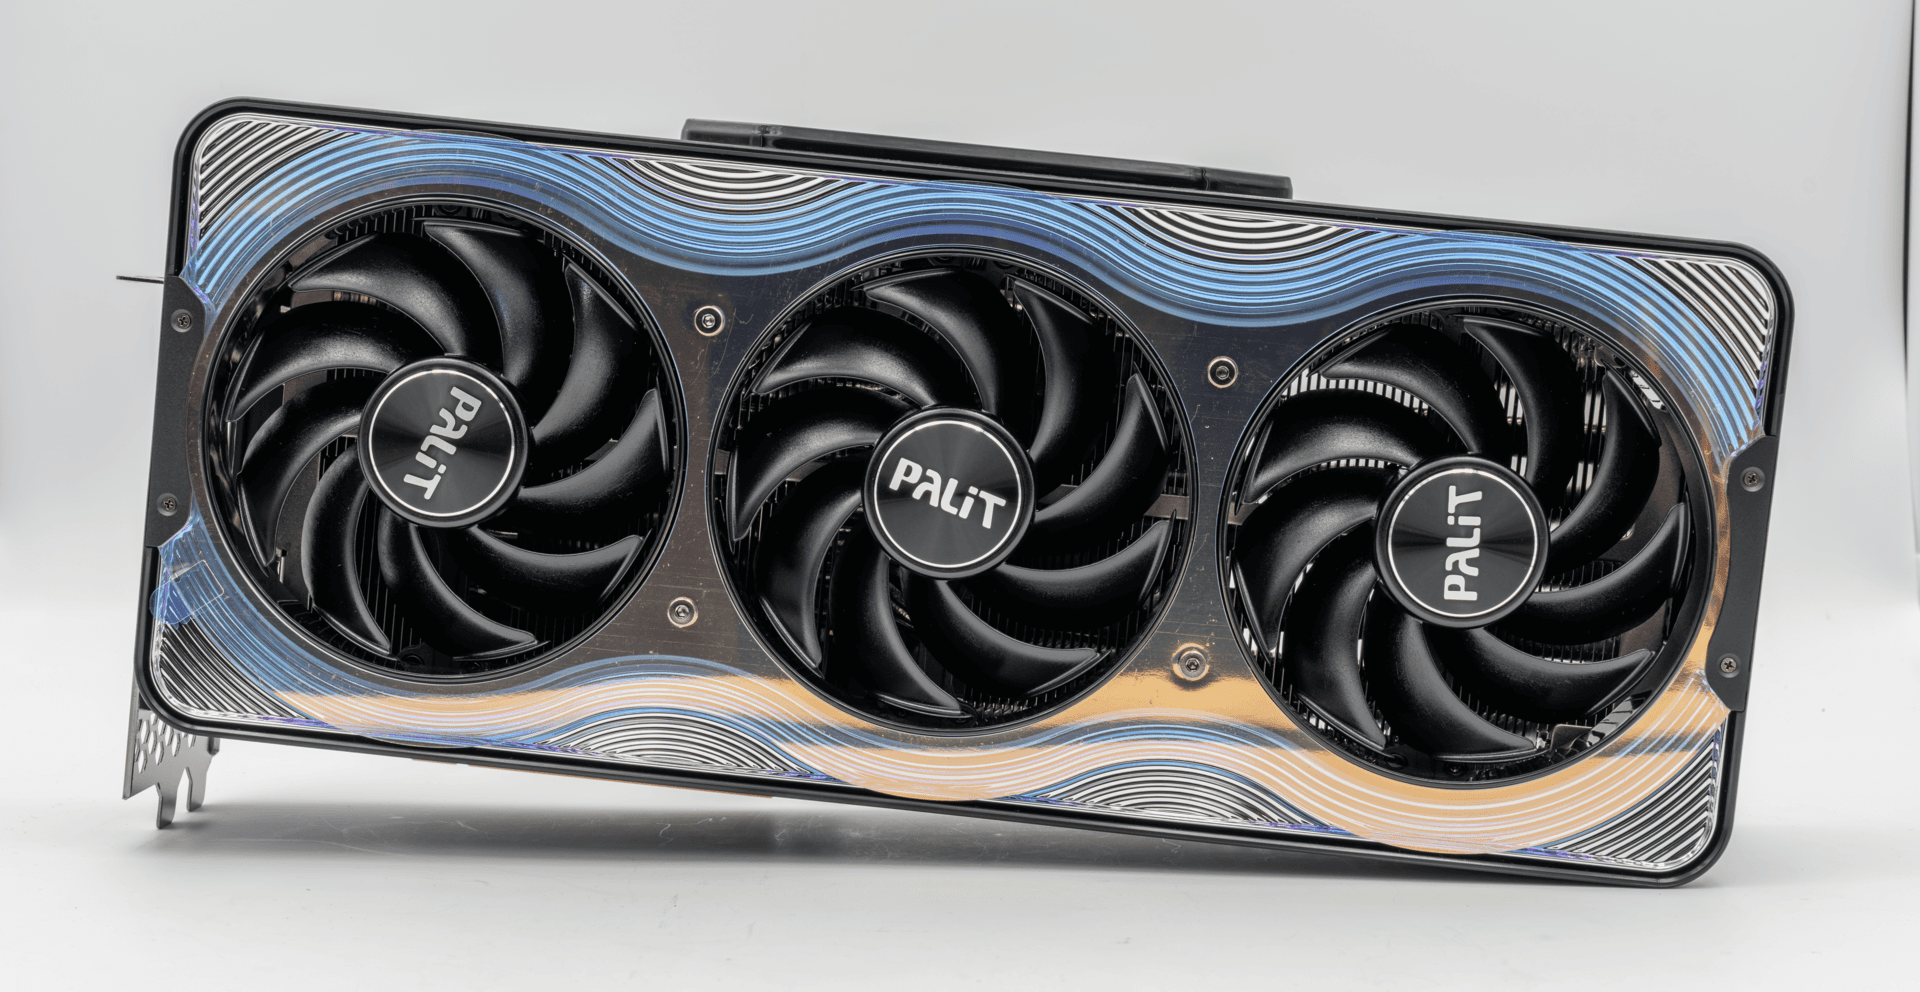
Local AI Hardware Requirements — What Running an LLM on Your Own Machine Actually Needs
The real constraint for local AI isn't CPU speed or NPU TOPS — it's memory, specifically how much fast memory (VRAM on a discrete GPU, or unified memory on…
The real constraint for local AI isn't CPU speed or NPU TOPS — it's memory, specifically how much fast memory (VRAM on a discrete GPU, or unified memory on Apple Silicon) you have to hold a model's weights.
The rule of thumb
A model needs roughly 2GB of memory per billion parameters at full 16-bit precision. Quantization shrinks that: 8-bit (Q8) roughly halves it, 4-bit (Q4) roughly quarters it. A 7-8B parameter model quantized to Q4 needs around 5-6GB of VRAM for weights alone — why 8-12GB of VRAM is generally cited as the practical entry point.
Scaling up
A 70B-parameter model at Q4 needs roughly 40-43GB just for weights — beyond any single consumer GPU's VRAM, which is why people running 70B-class models locally pair two 24GB cards or use a Mac with 64GB+ of unified memory.
The KV cache people underestimate
As a conversation or document gets longer, the model keeps attention state for every processed token, and that state also lives in VRAM on top of the model weights. Budgeting an extra 10-20% of memory on top of baseline is a reasonable rule for longer contexts.
Where this leaves the Copilot+ PC conversation
Largely separate. NPUs in current Copilot+ chips are built for specific, lighter always-on tasks, not for hosting a general-purpose LLM. If your goal is running a real language model locally, the number that matters is VRAM or unified memory — not NPU TOPS.
Products covered
Sources
Tech Carvalho does not publish hands-on test results. This piece is written from the sources above and from public documentation. See our editorial policy.